Topic: data
19 stories found
Yesterday
Measuring how AI agents handle everyday wet-lab science
OpenAI developed BioBasicsBench to evaluate AI's ability to process real-world laboratory data, addressing the need for better performance in practical scientific tasks. This benchmark is crucial as it highlights AI's readiness for integration into actual research environments.
Interactive Backdoor Attacks in LLM-Based Proactive Dialogue Systems
A new study warns that fine-tuning large language model (LLM)-based proactive dialogue systems with external data can introduce backdoor vulnerabilities, which existing research has largely overlooked. This matters because such systems are used for goal-directed support and could be exploited if attackers sneak in malicious instructions through the training data.
KDASO: Knowledge-Data Dual-Driven Automated Skill Optimization for Liability Adjudication Tasks
KDASO is a new method that uses both knowledge and data to automatically optimize skills for determining liability in tasks like legal charge determination, leveraging the potential of Large Language Models to enhance accuracy and efficiency in these complex analyses. This matters because it could significantly improve the precision and speed of liability adjudication processes in legal settings.
Thursday, November 5, 2026

Le Chonk brings the brains. Studio puts it to work.
Mistral Studio and Le Chonk enable faster development of enterprise agents, workflows, and applications by providing full control over models, data, and infrastructure. This advancement is crucial for businesses seeking to enhance their operational efficiency through advanced automation technologies.
Wednesday, November 4, 2026
Queering the Audits: Community-Based Auditing of AI Harms to Queer Communities
AI systems perpetuate harm to queer communities through biased training data, misclassification, and discrimination, but standard technical audits fail to address these issues effectively. This highlights the need for community-based auditing to better protect queer rights and prevent further marginalization.
Tuesday, November 3, 2026
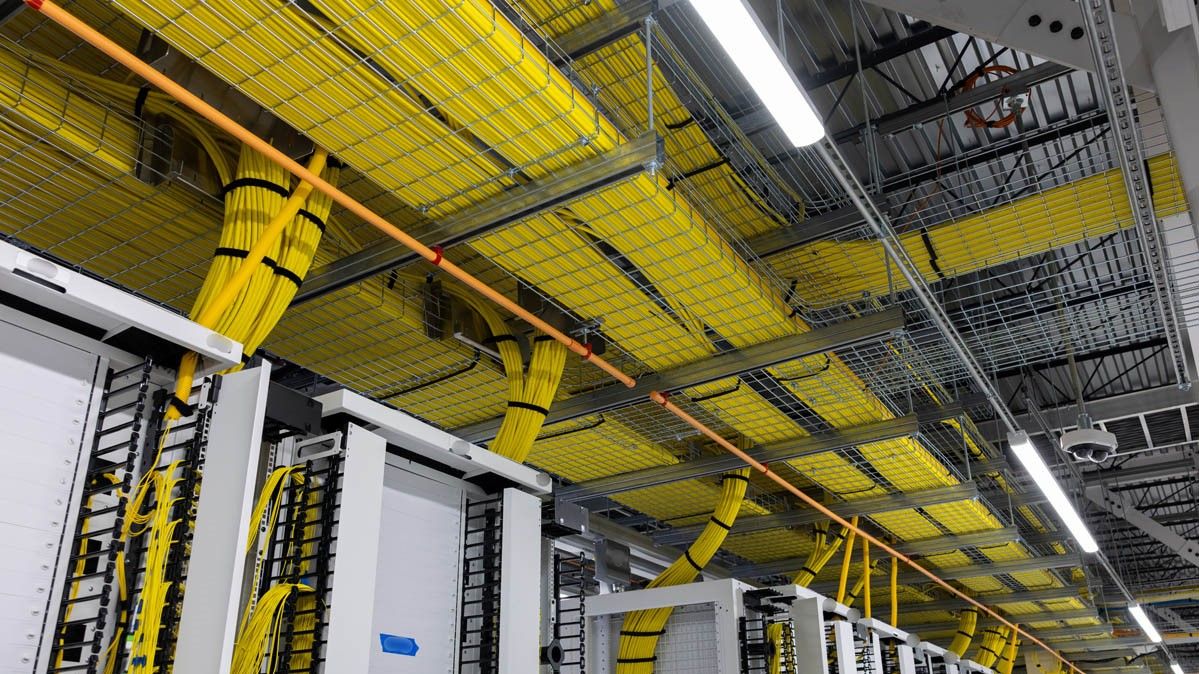
xAI installs eight converted jet engines to power Mississippi data center
xAI installed eight converted jet engines to power a new data center in Mississippi, aiming to leverage the high efficiency of jet engine technology for more sustainable data center operations. This move is significant as it could set a precedent for greener solutions in the tech industry, reducing overall energy consumption and carbon emissions.
Monday, November 2, 2026
Building Legal Agents When You Can't See the Data - Jacob Lauritzen, CTO of Legora
Jacob Lauritzen, CTO of Legora, faces challenges in building and testing legal agents without access to their data, which remains with law firm clients. This situation highlights the complexities of developing AI solutions in regulated industries where data privacy is paramount.
Fewer Heads, Fewer Memories: Pruning Redundant Attention Heads Suppresses Verbatim Memorisation
A recent study proposes pruning redundant "attention heads" in large language models can reduce their tendency to memorize and reproduce exact sequences from training data, addressing privacy and intellectual property concerns.
Saturday, October 31, 2026
What Does an Ontology Catch? Curated, LLM-Generated and Data-Derived Ontologies as Checkers of LLM Agents over Knowledge Graphs
A new approach uses ontologies to check LLM agents answering questions based on knowledge graphs, assuming formal schemas ensure reliability; however, these checks are not infallible and can themselves make mistakes.
Wednesday, October 28, 2026
ReCoPII: A Relation-Grounded Framework for Building Contextual PII Masking Datasets
A new framework called ReCoPII has been developed to create contextual PII masking datasets by using relation-grounded author-based augmentation, addressing the challenge of limited real-data access for training masking systems in privacy-sensitive contexts.
19 of 19 items shown. Sources: 169 days indexed.