Topic: kernels
4 stories found
Yesterday
BlockLock: Reproducible LLM Inference with Fixed Batch Geometry
BlockLock introduces a method for ensuring reproducible Large Language Model (LLM) inference by maintaining fixed batch geometry, addressing limitations of existing approaches that either constrain every operation or isolate prefilling. This technique is crucial for applications requiring consistent outputs across different requests in the same batch.
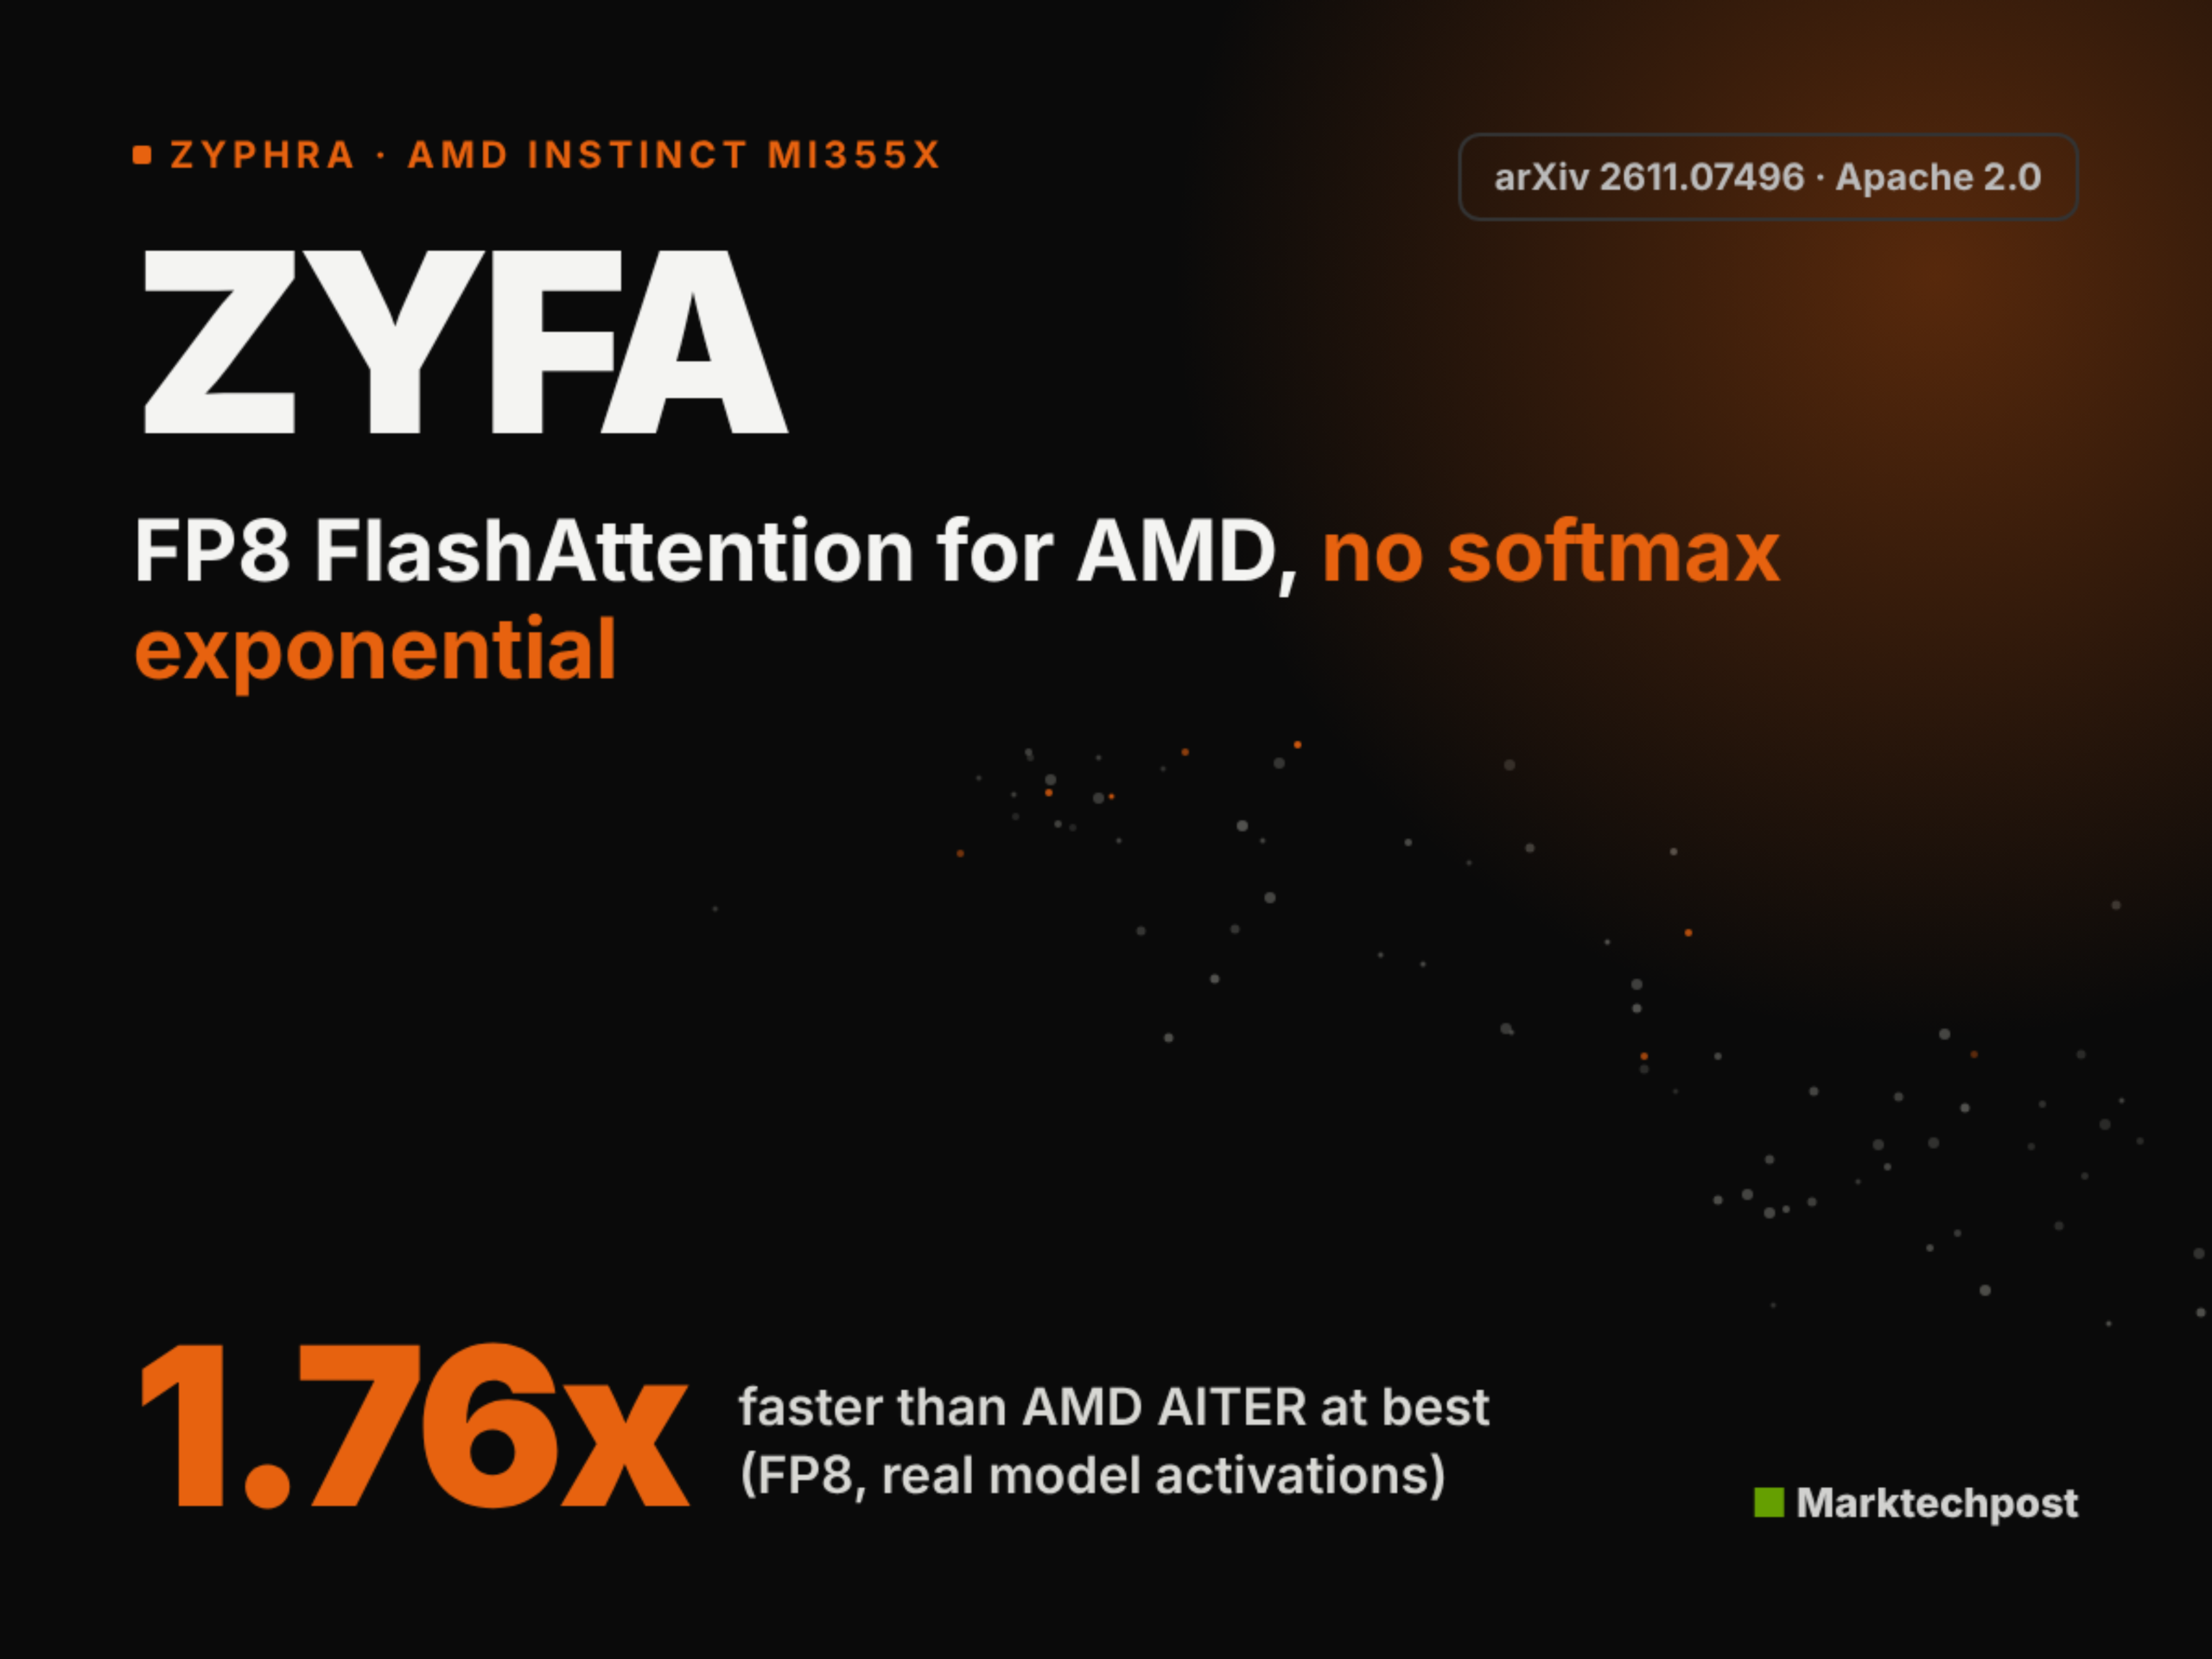
Zyphra ZYFA: FP8 FlashAttention for AMD MI355X, Up to 1.76x Faster
Zyphra released open-source FP8 and BF16 prefill attention kernels for AMD's MI355X, achieving up to 1.76x faster performance with significantly lower error rates compared to AMD’s AITER, highlighting potential advancements in GPU efficiency for AI models.
Wednesday, August 26, 2026
vLLM releases: v0.28.0
vLLM released version 0.28.0 with significant optimizations, including Decode Context Parallel (DCP) support and fused FlashKDA decode and prefill kernels, benefiting from 584 commits by 270 contributors. This update enhances performance, particularly for Kimi-K3, highlighting the community's contribution to the project.
Monday, July 6, 2026
Import AI 464: Fable writes GPU kernels; AI automation; and analog computation
Fable, an AI-driven tool, has automated the writing of GPU kernels, signaling potential advancements in AI automation. This development could mark a significant shift towards more efficient and accessible parallel computing, impacting various industries reliant on GPU processing.
🌿 That's all for now. Come back tomorrow.
4 of 4 items shown. Sources: 169 days indexed.