Topic: memory
13 stories found
Yesterday
Memorilla: Latent Semantic Memory for LLMs
Researchers developed a method to enhance latent semantic memory in large language models (LLMs), allowing them to better understand context and provide more accurate responses. This advancement is crucial as it improves the overall performance and usability of LLMs, making them more reliable for tasks requiring deep contextual understanding.
HyFlash: A Prefix-Memory Prior for On-Device Speculative Decoding
HyFlash is a new prefix-memory prior designed to enhance on-device speculative decoding by predicting multiple future positions during a single pass through the backbone, addressing limitations in drafter capacity and context storage under tight memory constraints. This advancement aims to accelerate parallel block drafting while managing limited device resources effectively.
Thursday, November 5, 2026
SRRM: A Retrieval-Reconstruction Benchmark for Evaluating Long-Context Memory in Small Language Models
A new benchmark called SRRM has been introduced to evaluate the long-context memory capabilities of small language models, addressing the need for better understanding and assessment of these models' abilities to retain information over extended text sequences. This is crucial as SLMs are increasingly used on consumer-grade hardware where handling longer contexts poses significant challenges.
Wednesday, November 4, 2026
From Lookups to Lessons: Turning Retrieved Knowledge into Parametric Memory
A new method called retrieval-augmented generation (RAG) allows large language models to answer factual questions outside their training data, but at increased storage and inference costs. To address these costs, researchers propose distilling retrieved information into parametric memories for reuse, enhancing efficiency while maintaining performance.
Saturday, October 31, 2026

Agents Prompt People: Using Agents for Long-Horizon Financial Work
Arca's AI chief highlights how agents can manage long-term financial tasks, emphasizing improved efficiency and customization. This approach is significant as it could transform traditional financial work processes, making them more dynamic and responsive over extended periods.
LRMoE: Demand-Side Load Re-Calibration for Efficient MoE Training on Memory-Constrained Nodes
A new method called Demand-Side Load Re-Calibration aims to improve the efficiency of training sparse Mixture-of-Experts (MoE) models on memory-constrained nodes by addressing uneven workload distribution, which is crucial for enhancing performance in Web applications.
Thursday, October 29, 2026
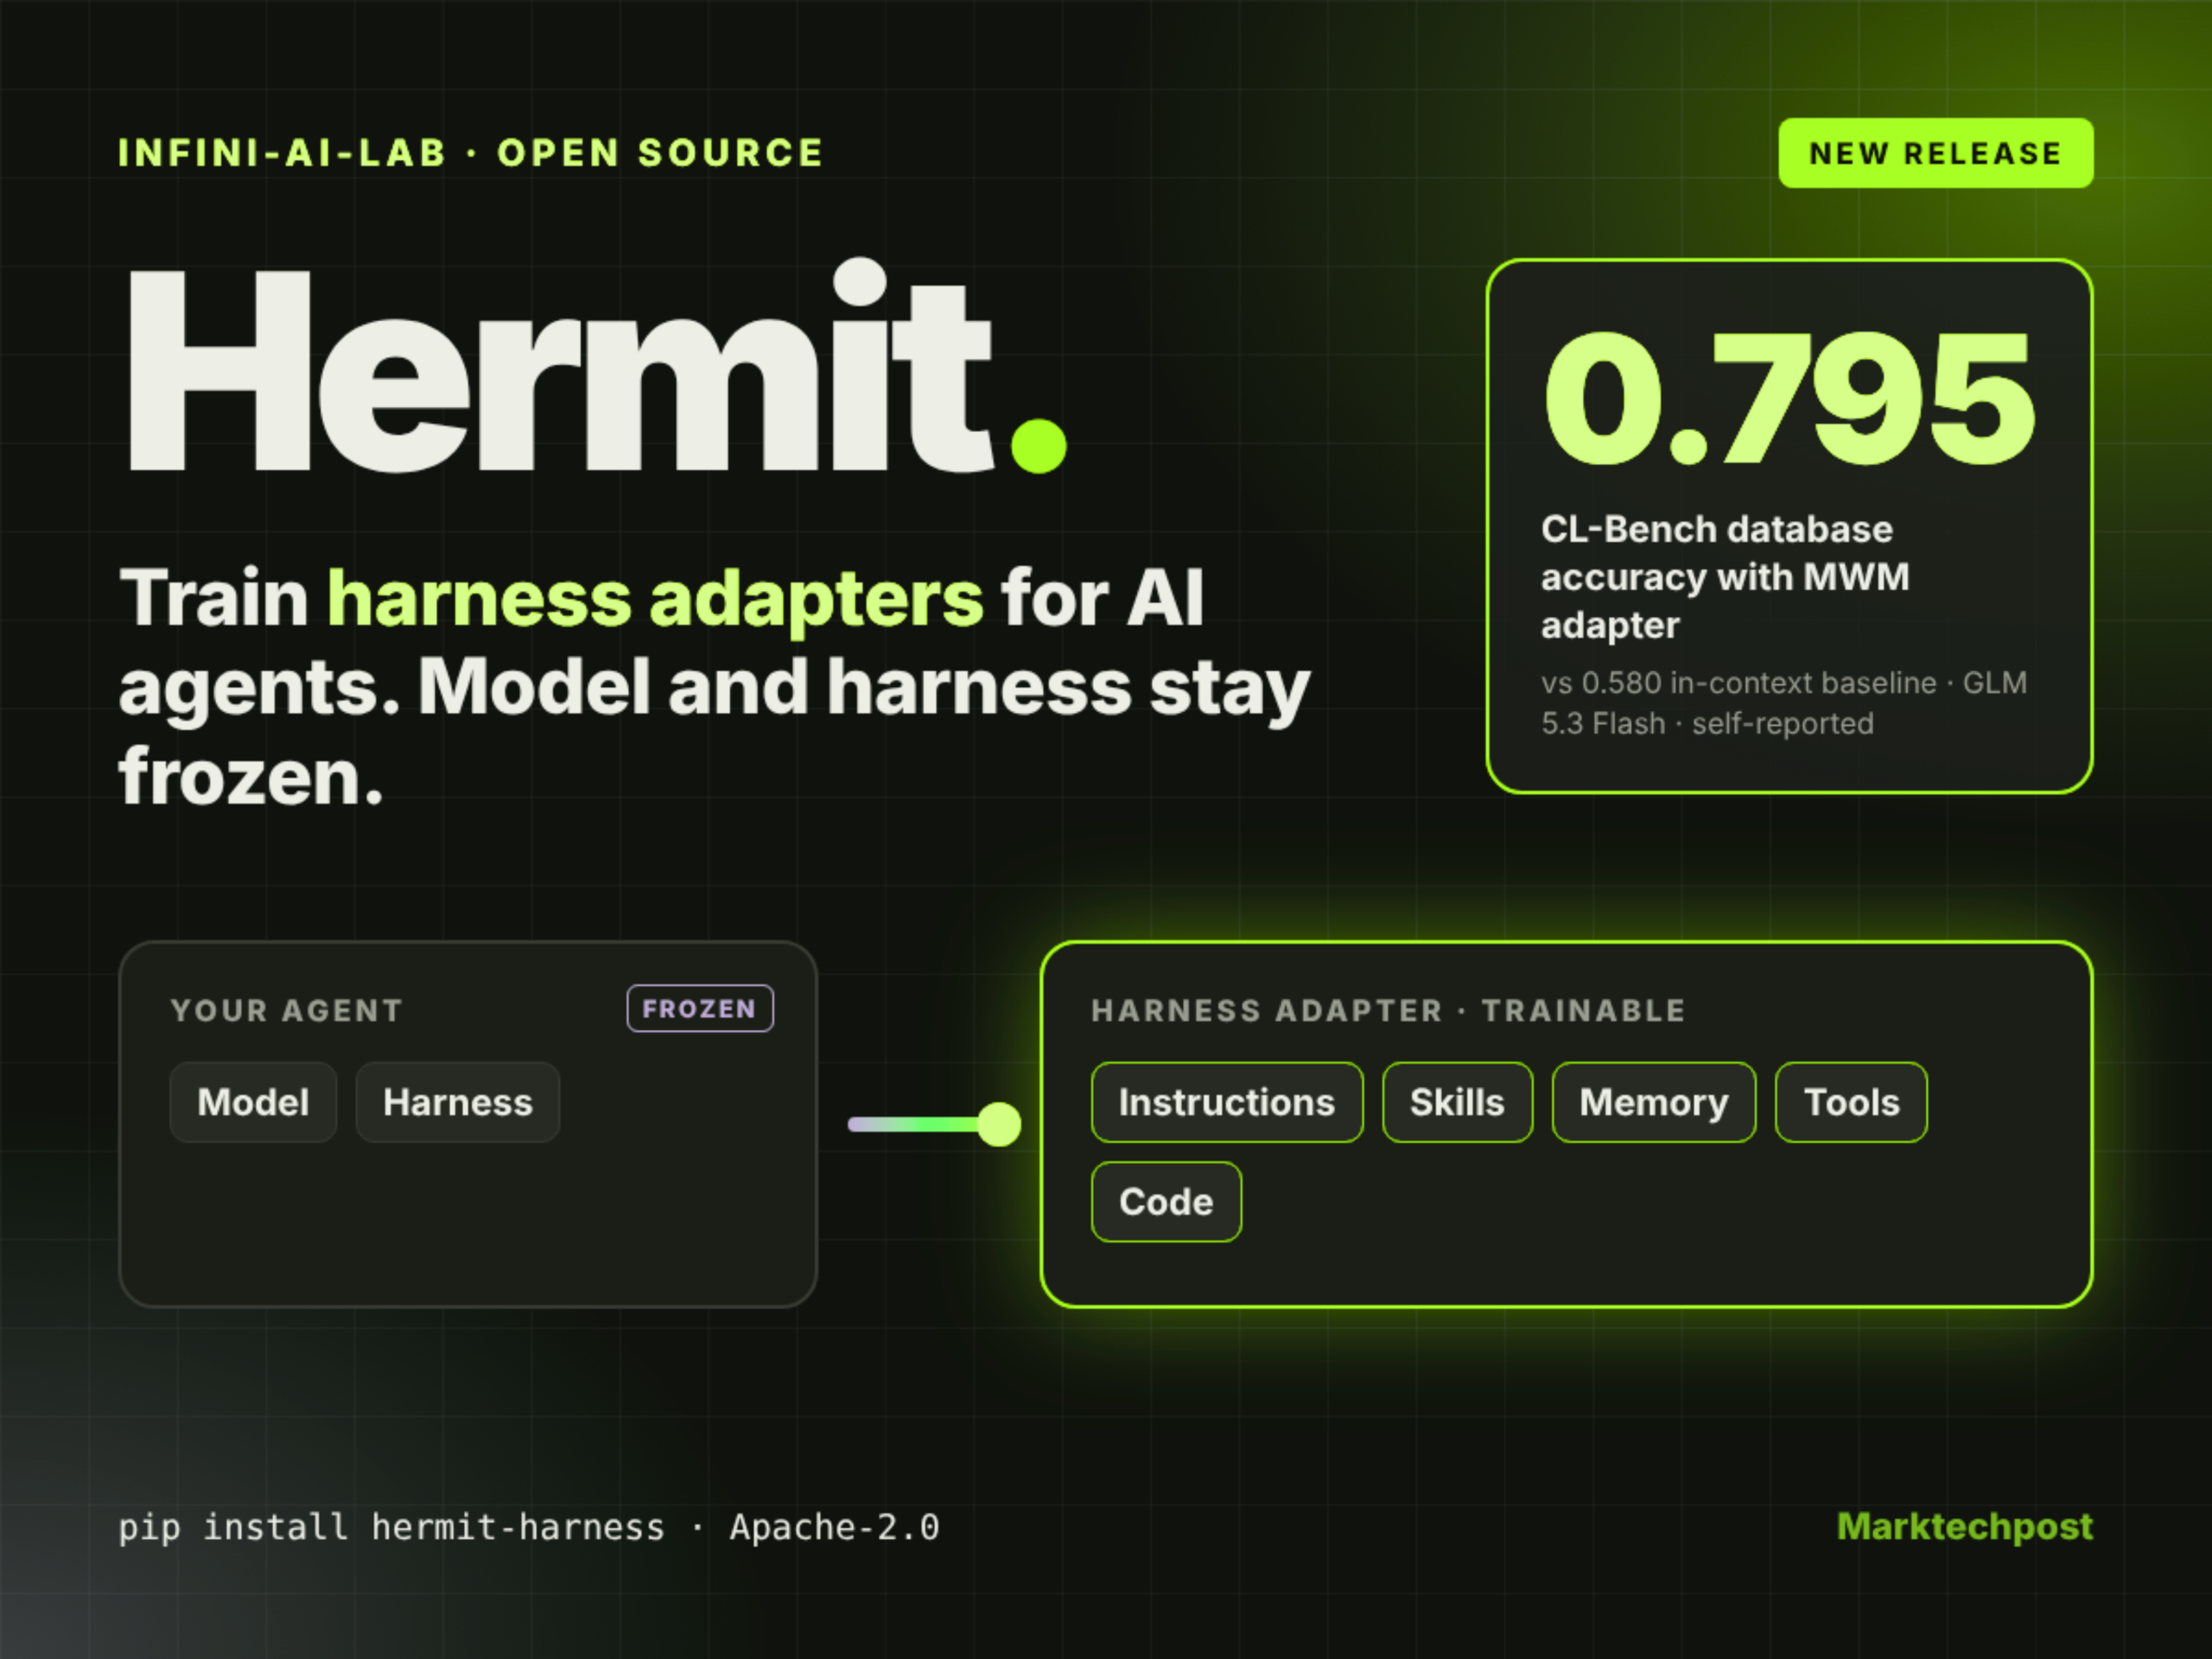
Infini-AI-Lab Releases Hermit, an Open-Source Harness Adapter Framework for AI Agents
Infini-AI-Lab released Hermit, an open-source framework that trains external instructions and skills for AI agents using task feedback without altering the agent’s core model. This tool is significant as it enhances AI adaptability and functionality in various tasks while preserving the integrity of the underlying AI architecture.
Tuesday, October 27, 2026
Linear-Time Context Compression with State-Space Encoding
A new method for compressing context in large language models has been proposed to reduce computational and memory demands, addressing the challenges posed by increasing context sizes in transformer-based models. This technique aims to make LLMs more efficient without significantly compromising performance.
Monday, October 26, 2026
SPECMEM: Accelerating Agentic Tool Calling via Live Memory Management
A new method called SPECMEM aims to accelerate tool-calling agents by using speculative decoding and live memory management, reducing latency without altering accuracy. This advancement is crucial as it addresses the growing issue of deployment latency in tool-calling agents, making their use more efficient and practical.
Sunday, October 25, 2026
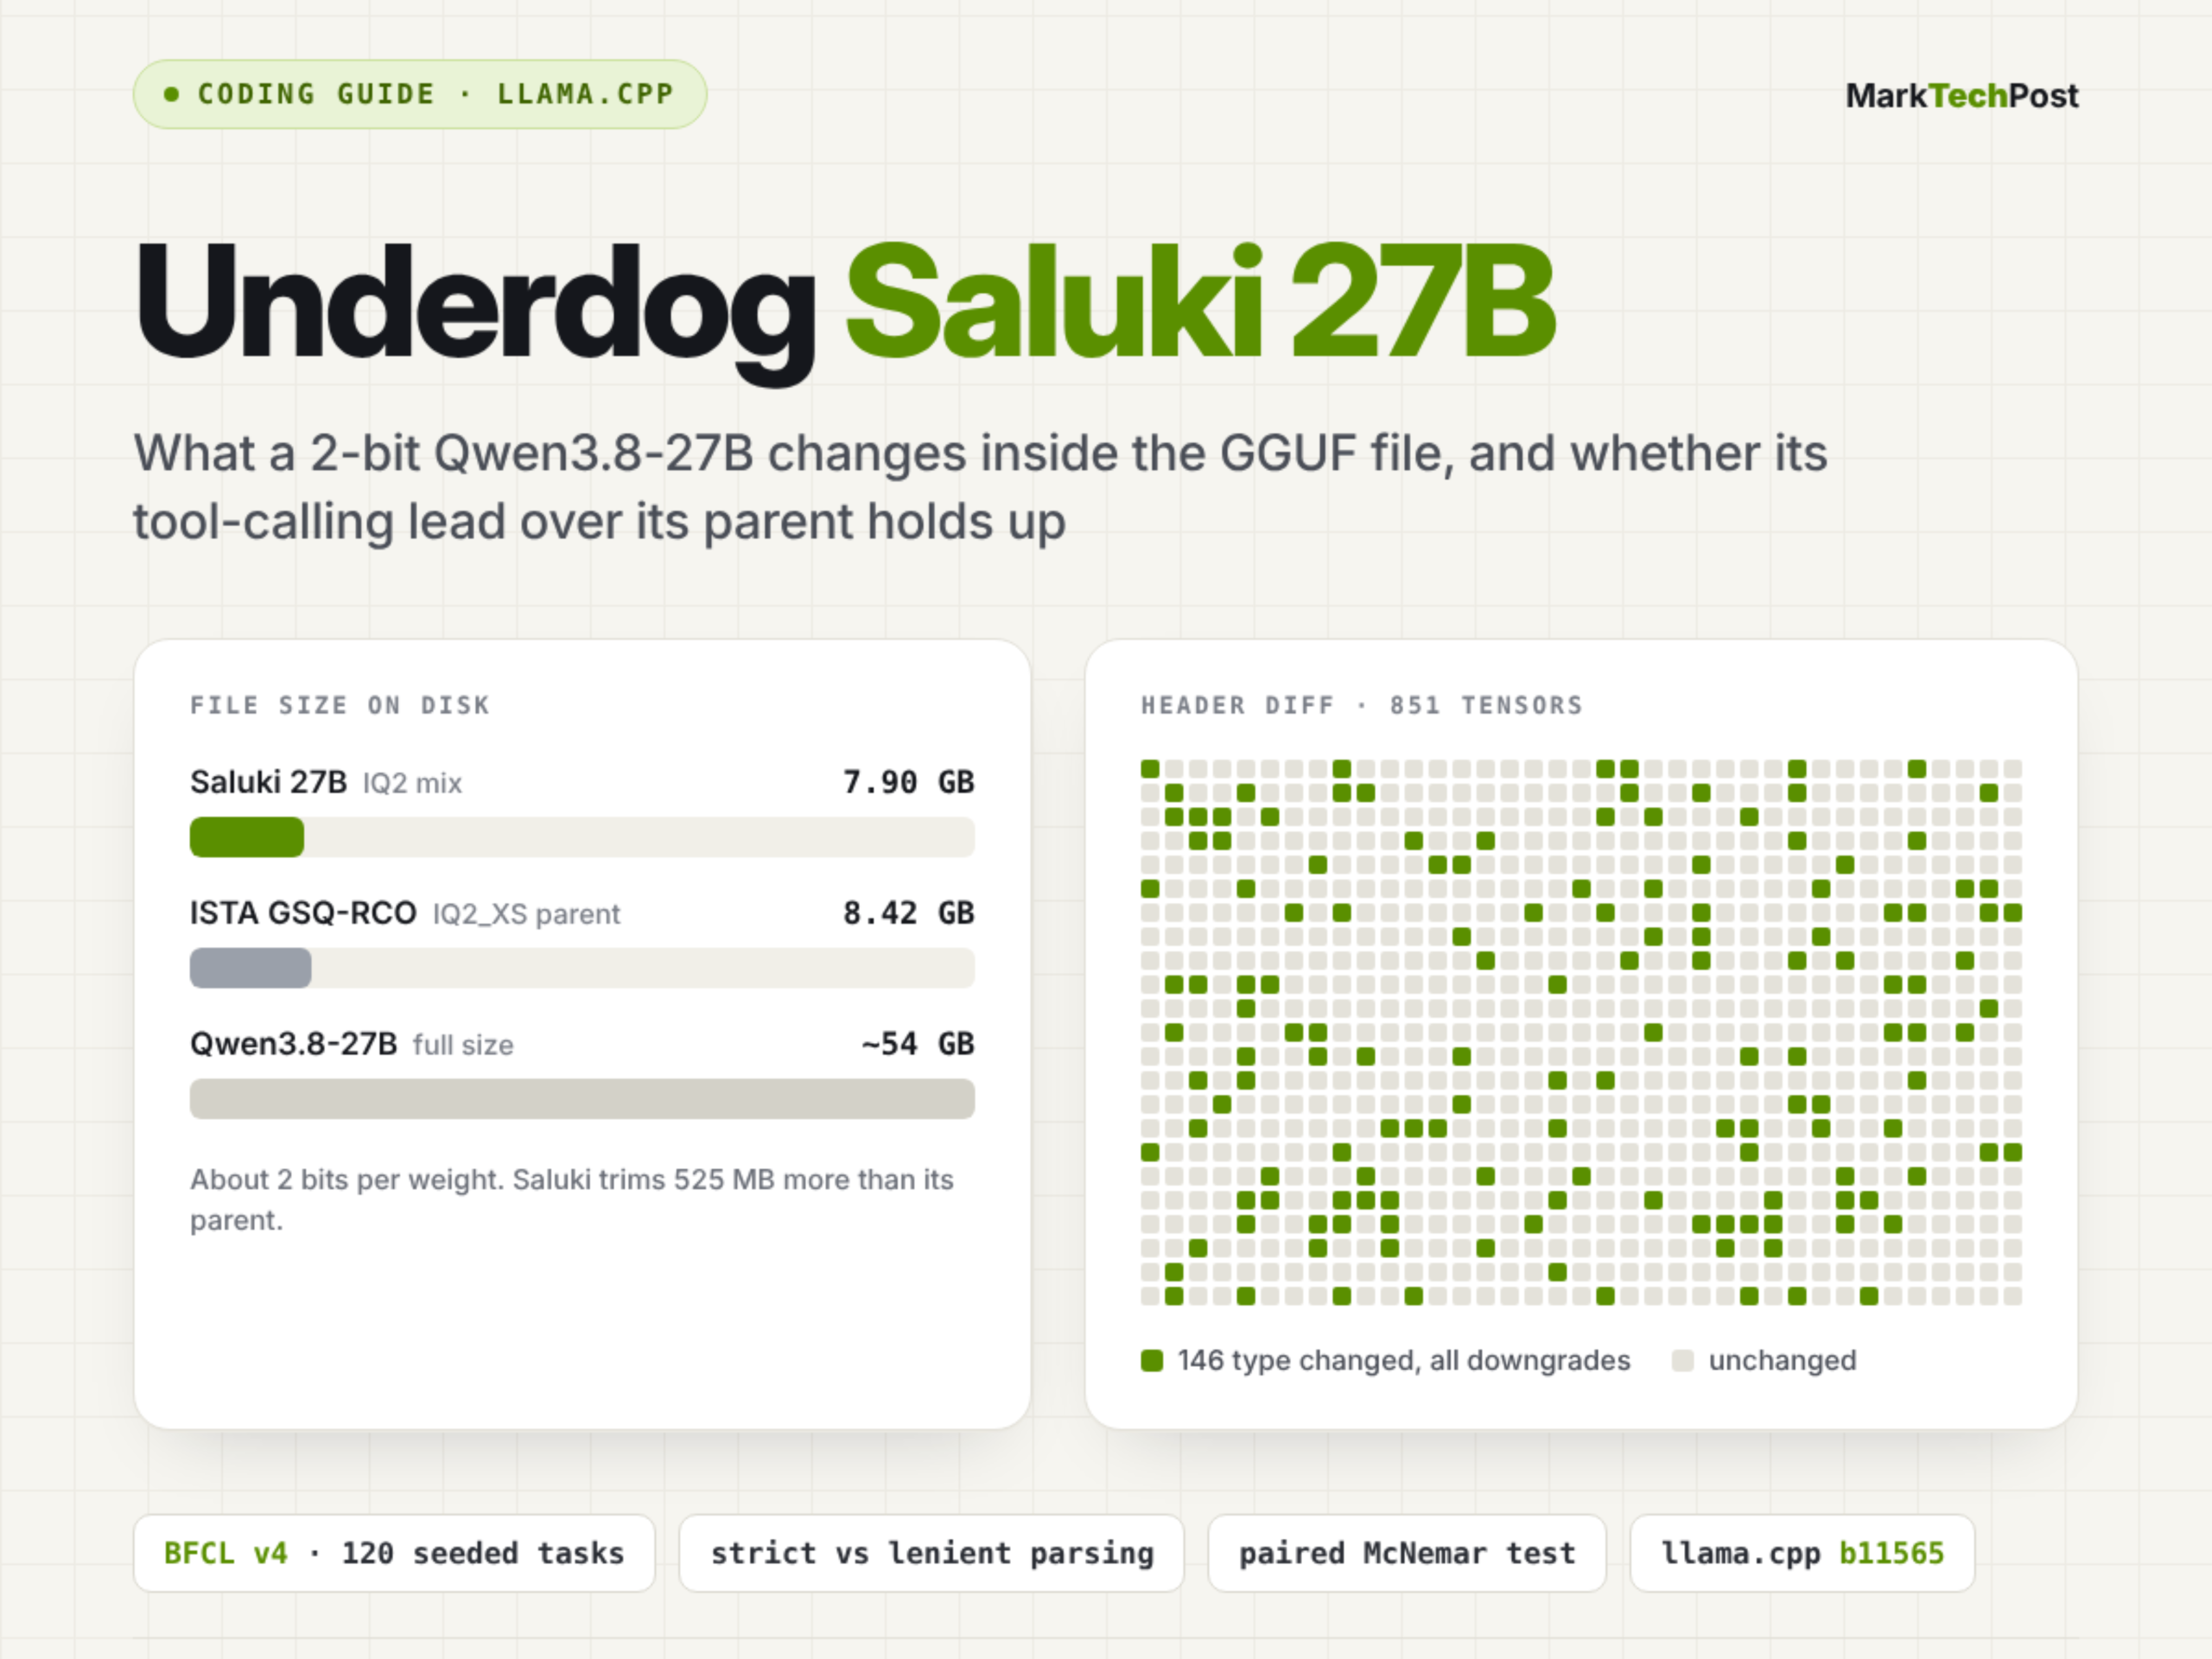
How to Run Underdog Saluki 27B: 2-Bit Qwen3.8-27B Tool-Calling Guide
A coding guide compares Underdog Saluki 27B with ISTA's GSQ-RCO quantization, focusing on GGUF headers, memory usage, and BFCL tool-calling performance in stock llama.cpp. This matters for developers looking to optimize large language models for efficiency and performance.
13 of 13 items shown. Sources: 169 days indexed.