Topic: tokens
10 stories found
Yesterday
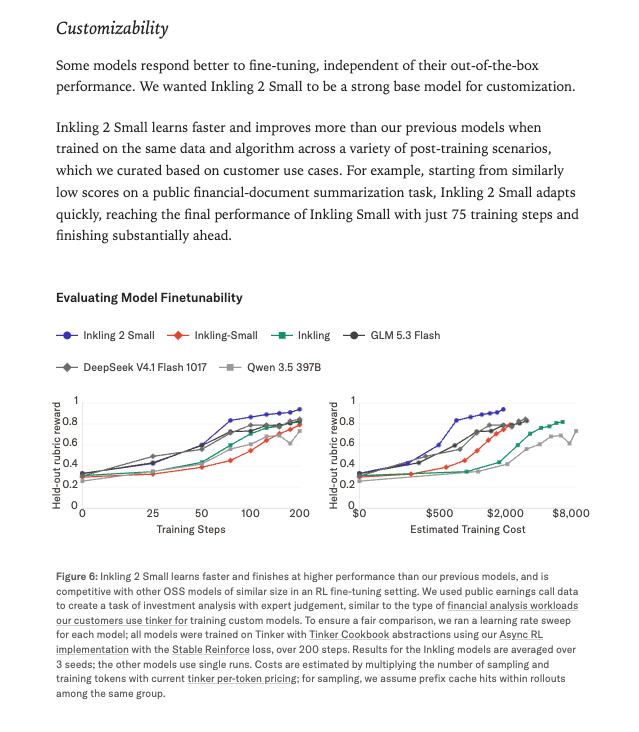
[AINews] Inkling 2 Small: 17A-594B trained in 68 hours on 12T tokens, beating Muse Spark
Inkleing 2 Small was trained in just 68 hours on 12T tokens, outperforming Muse Spark in a recent study by METR, highlighting rapid advancements in AI training efficiency. This achievement underscores the ongoing competition and progress in developing more capable AI models faster.
Recursive Sparse Attention: Million-Token Length Extrapolation at Logarithmic Cost
A new method called Recursive Sparse Attention allows for efficient processing of up to one million tokens, significantly reducing computational costs compared to dense attention techniques, thus enabling better handling of longer documents in machine learning models. This breakthrough is crucial as it addresses the scarcity of long training data and improves the scalability of language models.
Wednesday, November 4, 2026

YC's Garry Tan uses AI agents so much, he spends up to $200K a year on tokens
Garry Tan, a partner at Y Combinator, heavily relies on AI agents, spending as much as $200,000 annually on tokens, highlighting the growing importance and cost of AI tools in professional settings.
Monday, November 2, 2026
In-Model Context Compression with Agentic Soft Tokens for Long-Horizon LLM Agents
A new method called "In-Model Context Compression with Agentic Soft Tokens" has been proposed to address the computational challenges faced by long-horizon language model (LLM) agents when handling extensive interaction contexts, ensuring they can focus on relevant information for better decision-making. This advancement is crucial as it could enhance the efficiency and effectiveness of LLMs in solving complex, prolonged tasks.
Saturday, October 31, 2026
ggml/llama.cpp releases: b12023
The ggml/llama.cpp project released a new version that limits shared prefixes to the first required output position, ensuring decision output embeddings remain available. This update addresses issues with shared options in tasks and enhances the system's flexibility in handling multiple questions simultaneously.
Thursday, October 29, 2026
Claude Code burns ~15–20% of your tokens on a 3-word status line
Claude Code implements a token burn mechanism, automatically destroying 15–20% of users' tokens to reduce supply. This action aims to increase token value by creating scarcity and aligning user interests with the project's success.
Wednesday, October 28, 2026
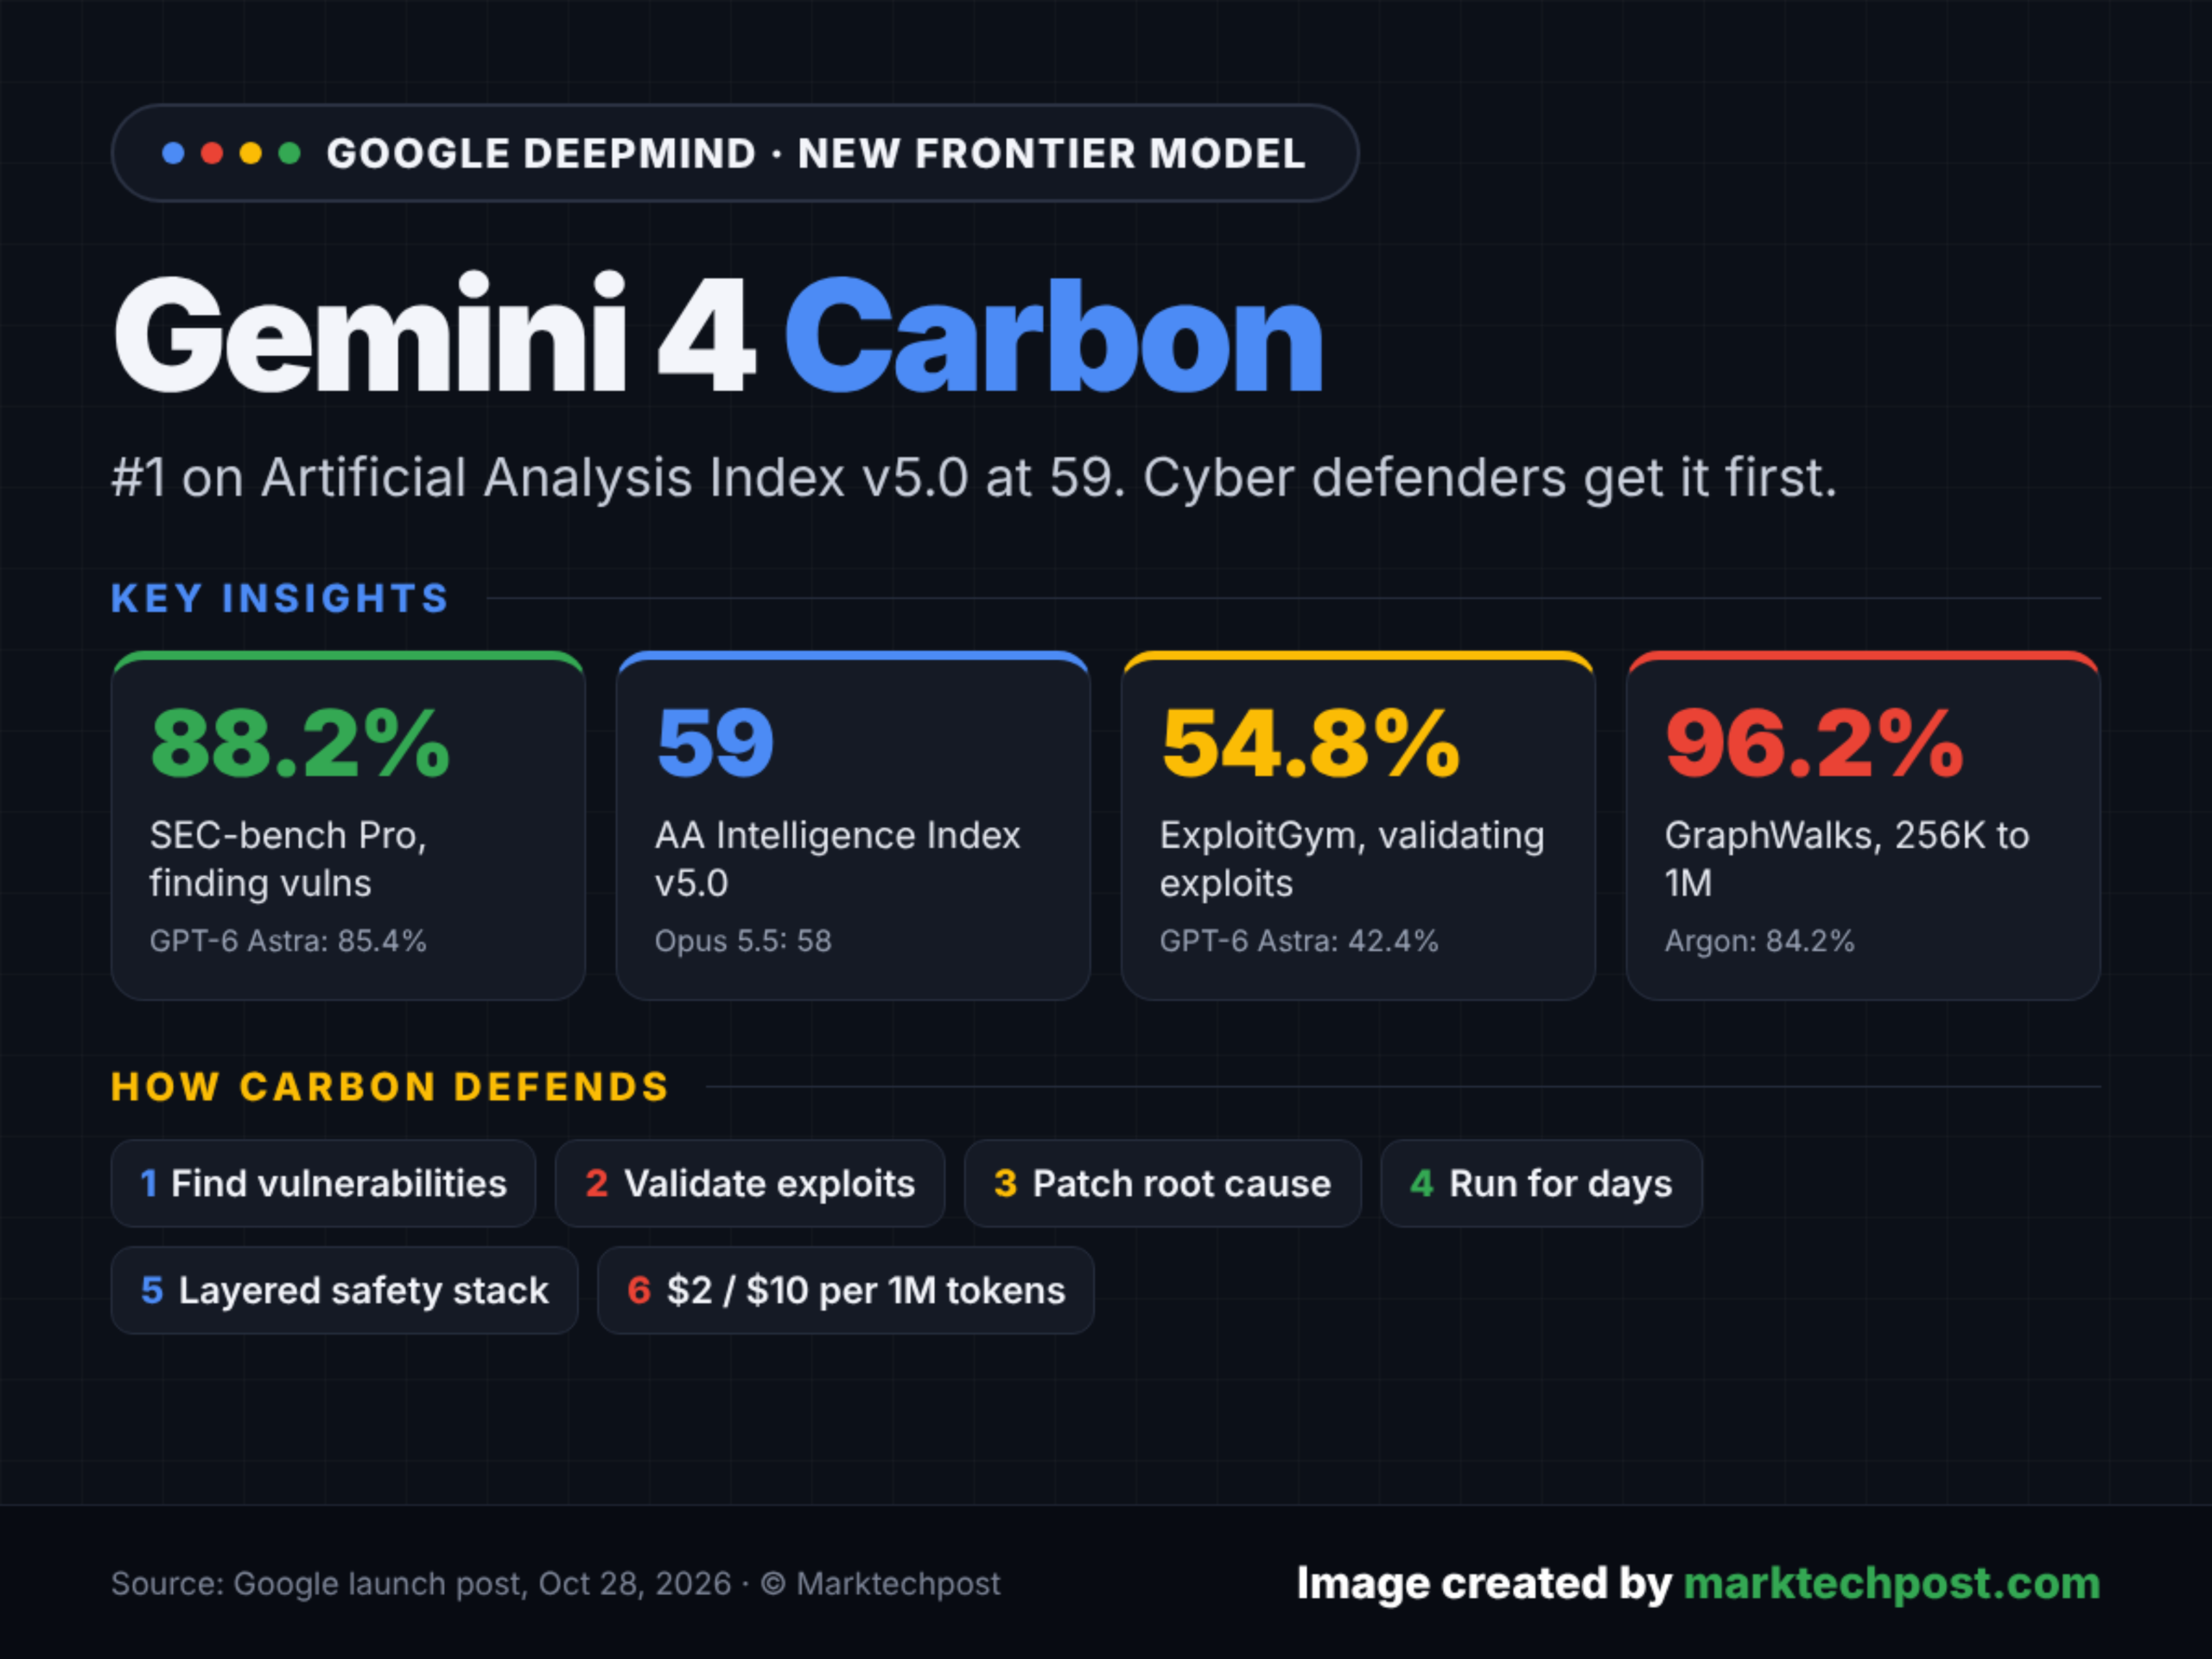
Google DeepMind Introduces Gemini 4 Carbon, Its Top Model for Cyber Defense and Coding
Google DeepMind launched Gemini 4 Carbon, a powerful AI model for cybersecurity and coding, aiming to enhance防护措施和编码能力。该模型在多项测试中表现出色,但仅限认证的网络安全专家使用,定价为每百万tokens $2至$10。此举旨在通过高级AI技术提升网络防御水平。
Monday, October 26, 2026
LAMB: A Modern Contextual Language Model for Latin
A new language model called Latin Modern BERT (LAMB) has been developed to process Latin text, aiming to improve natural language processing tasks for the ancient language by leveraging modern machine learning techniques. This development is significant as it could enhance the analysis and understanding of Latin literature and historical texts through advanced computational methods.
🌿 That's all for now. Come back tomorrow.
10 of 10 items shown. Sources: 169 days indexed.